Sanity Context: Ground AI in Trusted CMS Content
Use Sanity Context and Knowledge Bases to ground AI assistants in trusted CMS content with practical access, testing, freshness and governance controls.
Sanity's documentation team said on 30 October 2026 that its own Ask AI experience now runs on Sanity Context and Knowledge Bases. That first-party example makes the product timely for businesses considering customer support assistants, staff knowledge tools, product advisers or editorial research agents.
The commercial promise is straightforward: let an AI assistant retrieve approved business content instead of relying only on model training data or an ungoverned folder of files. The implementation is not a plug-and-play chatbot. Sanity provides a hosted, read-only Model Context Protocol (MCP) layer; the business still supplies the model, agent application, interface, testing, privacy controls and operational ownership.
This guide explains where live CMS retrieval fits, when a pre-built Knowledge Base is better, how to prevent unpublished content from leaking into answers and how an Australian SME can run a narrow pilot with measurable acceptance criteria.
VaniTech supports CMS implementation, AI workflow development, system integration and ongoing technical support.
Three Changes Make Grounded AI More Practical
Sanity has moved from an abstract RAG pattern to a documented, testable content-access layer.
First-Party Proof
Sanity's own Ask AI now uses the same Context and Knowledge Base capabilities available to customers.
Two Retrieval Modes
Teams can query structured CMS data live or serve a reconciled index built from datasets, websites and files.
Deployable Controls
New security, quick-start and Blueprints guidance makes access scope and infrastructure ownership clearer.
What Sanity Context is—and what it is not
Sanity Context is a hosted, read-only MCP server. It gives an AI agent a structured way to retrieve content from Sanity without giving that retrieval layer permission to modify the dataset. In live dataset mode, the agent uses GROQ tools and the deployed schema. In Knowledge Base mode, it reads from an index that Sanity builds ahead of time.
Sanity hosts the endpoint and content-access configuration. You bring the AI model, the agent loop, the user experience and the business rules. That separation is useful because a team can change which approved sources an endpoint serves without rebuilding the entire assistant, but it also means Sanity Context does not remove the need for application architecture, privacy review, observability or support.
Context MCP is not the same as Sanity's write-capable MCP server. It cannot create, edit or publish CMS documents. A customer-support assistant can retrieve a returns policy through Context, but any action such as issuing a refund, changing an order or publishing content needs a separate controlled integration.
Knowledge Bases are currently an opt-in beta. Confirm plan limits, support, change expectations and production suitability with Sanity before making a critical customer journey depend on them.
Choose live GROQ retrieval or a Knowledge Base
| Decision | GROQ mode | Knowledge Base mode |
|---|---|---|
| Best for | Structured, consistent CMS data | Answers spread across prose and several sources |
| Typical question | Which products are available in size L? | What is our return policy for a damaged bulk order? |
| Freshness | Queries the dataset at request time | Serves entries produced by the latest reviewed build |
| Source shape | Sanity documents with a deployed schema | Datasets, website pages and uploaded files |
| Conflict handling | The agent interprets live results | The build surfaces conflicts for review |
| Access boundary | Endpoint source plus server-side GROQ filter | Knowledge Bases attached to the endpoint |
Use live retrieval when the answer should come from current fields and predictable relationships: product specifications, service locations, event dates or published articles. Use a Knowledge Base when finding and reconciling the answer is the difficult part: support policies split across a website and PDFs, technical guidance spanning many articles, or internal procedures with repeated explanations.
Do not choose a Knowledge Base simply because the phrase sounds more AI-ready. A clean content model and a precise live query are often easier to test and keep current than a second indexed representation.
Start with a bounded business question
A useful first assistant has a narrow audience, a defined question set and an accountable content owner. Good pilots include:
- a customer-support assistant that answers from approved delivery, returns and warranty policies;
- a staff assistant that retrieves current operating procedures and escalation contacts;
- a product adviser that filters structured catalogue data and explains approved specifications;
- an editorial research helper that checks existing coverage before a new article is commissioned.
Avoid an open-ended assistant that can search every draft, confidential file and customer record. Write down what it may answer, what it must refuse, which sources are authoritative and when it must hand the user to a person.
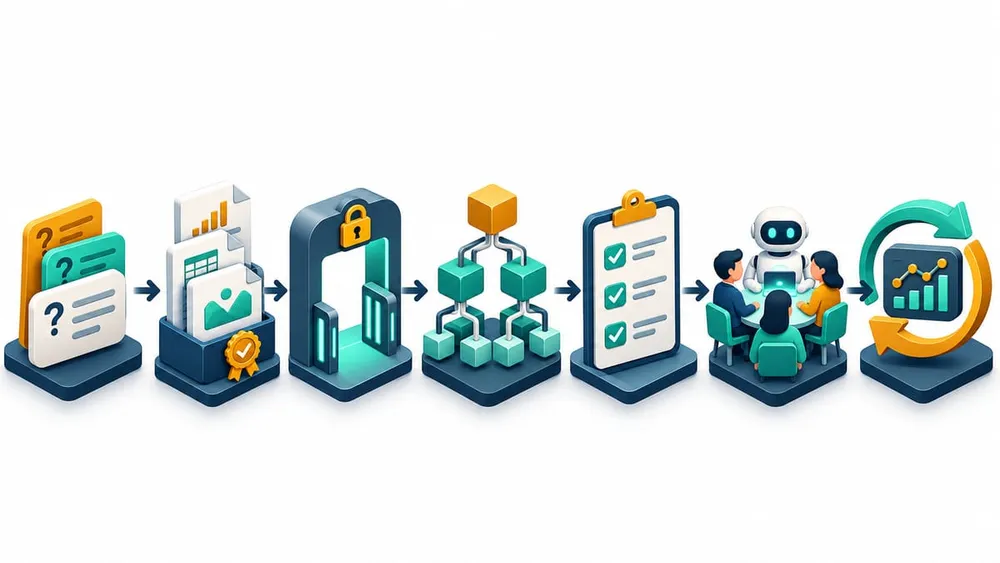
Define evidence for success before implementation: correct source selected, answer supported by the source, no prohibited material disclosed, uncertainty stated, escalation offered and response delivered within an acceptable time. Australian Government AI guidance recommends clear acceptance criteria, documented testing, accountable deployment authorisation and post-release monitoring.
Build the knowledge layer around trusted sources
A Sanity Knowledge Base has a purpose that describes who it serves and what it should help with. The build uses that purpose to organise an outline and mark central or peripheral material. Agents receive the outline as initial context, then fetch the entries most likely to answer a question.
Start with a small, current source set. Add the approved CMS dataset, the public help centre and the latest policy files—not every document a team can find. Each extra source increases the chance of duplicated or conflicting claims.
Sanity builds entries from the sources and preserves citations back to them. When two sources disagree, the build can raise an issue showing both claims. A reviewer can decide which source is authoritative, correct the underlying content and record a standing instruction for later builds. That is more useful than asking the model to improvise a choice every time the question appears.
Use the CMS as the system of record where possible. If a policy is corrected only inside the Knowledge Base, the website, call-centre script and downloadable PDF may continue to disagree. Fix the authoritative source, rebuild, review the resulting entries and retain evidence of the decision.
Treat access configuration as a security boundary
Context access is decided when the agent connects. The organization token authorises the connection, the endpoint configuration determines which sources it serves and a server-side groqFilter can narrow dataset reads. A caller can make that filter more restrictive but cannot widen it through a prompt or URL parameter.
Use an organization token with Context Viewer permission, keep it on the server and never expose it in browser code. Configure one endpoint per trust boundary where practical—for example, public support content should not share an endpoint with staff-only operating procedures.
There is an important draft-content warning. Sanity documents that a connected caller can request draft or raw perspectives for an attached dataset. If unpublished content is sensitive, do not attach that dataset. A filter such as _type == "article" && status == "published" helps scope the document set, but the overall dataset and field design still need a privacy review.
In Knowledge Base mode, the GROQ filter does not apply. The access boundary is the set of Knowledge Bases attached to the endpoint. Split public, partner and internal knowledge rather than serving one broad Knowledge Base to every assistant.
Keep the answer layer current
A refresh schedule does not automatically rewrite Knowledge Base entries. Sanity can recheck dataset and website sources weekly, monthly or on demand, then raise issues describing detected changes. The Knowledge Base continues serving its previous entries until the changes are reviewed and applied.
That behaviour protects a production assistant from silently changing after every source edit, but it creates an operating obligation. Assign a person to review issues, approve rebuilds and confirm high-risk answers after a change. Uploaded files are snapshots and are not rechecked, so replace outdated files deliberately.
Record four timestamps for each production Knowledge Base:
- when each source was last checked;
- when detected issues were last reviewed;
- when entries were last rebuilt;
- when the representative answer test suite last passed.
Sanity Blueprints can define Knowledge Bases and MCP endpoints as code. This is useful when environments, filters, sources and endpoint names must move through the same reviewed deployment process as the application.
Test answer quality, not just connectivity
| Test | Acceptance evidence | Failure to catch |
|---|---|---|
| Known-answer questions | Correct answer and authoritative source | Fluent answer from the wrong policy |
| Conflicting sources | Approved source wins or the assistant escalates | Agent blends incompatible rules |
| Missing answer | Uncertainty and human hand-off | Invented policy or product detail |
| Draft or restricted content | No disclosure in retrieval or response | Unpublished launch or internal procedure exposed |
| Prompt injection in a source | Source text cannot override system rules | Embedded instruction changes agent behaviour |
| Changed policy | Issue detected, reviewed and rebuilt | Old entry remains live without an owner |
| Tool or model failure | Safe error, trace and retry boundary | Empty or misleading customer response |
| Personal information | Collection and retention match the approved purpose | Chat transcript becomes an unmanaged customer record |
Measure grounded-answer accuracy, citation correctness, refusal quality, escalation rate, response time and repeated failure categories. Sanity Context Insights can record failed tool calls and failed turns for supported SDK versions, but operational telemetry does not replace a representative evaluation set reviewed by subject-matter owners.
Plan privacy and customer transparency
Read-only content retrieval does not make the whole assistant privacy-neutral. A website chatbot may collect names, account details, health information, order numbers or free-text descriptions from users. The model provider, logging service, analytics layer and support hand-off can each create another data flow.
OAIC guidance says privacy obligations apply to personal information entered into or produced by AI systems. It also recommends clearly identifying public-facing AI tools and assessing how personal information is collected, used, stored, disclosed and secured.
Before launch, map the complete interaction: browser, application, model, Context endpoint, transcript store, analytics, CRM or helpdesk and staff review. Minimise collected fields, provide a clear notice, set retention, restrict access and give users another support channel. Do not send customer data into the CMS knowledge layer merely because the assistant needs public policy content from the CMS.
Privacy Act coverage and sector duties vary. Obtain legal or privacy advice for the organisation and use case rather than treating a technical pattern as compliance advice.
A practical 30-day pilot for an Australian SME
Week 1: Bound the assistant
Choose one audience and 20–40 representative questions. Name the business owner, content owner, technical owner and support escalation. Classify public, internal and prohibited sources.
Week 2: Configure the context layer
Select GROQ or Knowledge Base mode, deploy the schema if required, create a dedicated endpoint, apply the narrowest source scope and store the Viewer token server-side. Build from a focused source set and resolve important conflicts.
Week 3: Build and test the assistant
Connect the model and interface, add refusal and escalation rules, then run known-answer, missing-answer, restricted-content, injection, privacy and failure tests. Record actual results against acceptance criteria.
Week 4: Release a supervised pilot
Limit users or traffic, display that the tool is AI-assisted, monitor conversations and review incorrect or ungrounded answers daily. Keep a simple off switch and a human fallback. Expand only after the assistant meets accuracy, privacy and operational targets.
Because Knowledge Bases are beta, include a portability plan. Preserve the source inventory, question set, endpoint configuration, acceptance results and application-level retrieval interface so the business can change the implementation without rebuilding governance from memory.
Questions to ask before adopting Sanity Context
- Which business questions should the assistant answer, and which must go to a person?
- Is each answer better served by live structured data or reconciled prose?
- Which source is authoritative when the website, PDF and CMS entry disagree?
- Can the endpoint reach drafts, raw content or fields that users should never see?
- Who reviews Knowledge Base issues and approves rebuilds?
- What beta limits, pricing, service commitments and change risks apply to the planned load?
- Where are model prompts, transcripts, citations, tool failures and user feedback retained?
- How will personal information be minimised and disclosed to users?
- What accuracy, refusal and escalation thresholds must pass before release?
- Who can pause the assistant and restore the last accepted configuration?
The best business case is not “we added a chatbot.” It is a specific customer or staff task completed faster, with current evidence and fewer incorrect answers. If that cannot be measured, keep the pilot small.
Sources Checked
- Sanity: Context and Knowledge Bases now power the Ask AI agent (30 October 2026)
- Sanity documentation: Sanity Context
- Sanity documentation: Knowledge Bases
- Sanity documentation: Context retrieval modes
- Sanity documentation: Content access and security
- Sanity documentation: Keep a Knowledge Base current
- Sanity documentation: Connect an agent to Sanity Context
- Sanity documentation: Define Context with Blueprints
- Sanity changelog: Failed tool calls and turns in Insights
- Australian Government: Guidance for AI Adoption implementation practices
- OAIC: Privacy and commercially available AI products
Common Business and Implementation Questions
Short answers for business owners, digital teams and technology decision-makers.
Need AI Answers Based on Trusted Business Content?
VaniTech can connect your CMS, knowledge sources and business systems to a tested AI assistant with practical access, privacy, monitoring and support controls.