Contentstack limit=0 Change: Fix API Pagination
Contentstack changed limit=0 API behaviour. Audit integrations, add explicit pagination, verify complete datasets and monitor record totals.
Contentstack announced on 11 September 2026 that the limit query parameter for Content Delivery API and Content Management API requests now accepts positive integers only. A request using limit=0, an empty value or a non-numeric value now receives the default number of records for that resource instead of all matching records.
That sounds like a small API cleanup, but the failure mode matters. A legacy export, search-indexing job, static-site build, migration script or reporting feed may still receive HTTP 200 while processing only the first page. Contentstack documents 100 records as the common default, so a completeness problem can look like a successful run.
This guide is for Australian business owners, digital and marketing leaders, developers, operations teams and technology decision-makers who rely on Contentstack websites, apps or connected systems.
Three facts to put on the integration plan
The risk is silent partial data, not necessarily an obvious API failure.
11 September 2026
Contentstack announced the behavioural change for limit in CDA and CMA requests.
Positive integers only
Zero, empty and non-numeric values now fall back to the resource default instead of requesting every match.
Often 100 records
Contentstack documents 100 as a common first-page default, making completeness checks essential for larger datasets.
What changed and why it can be easy to miss
Before the change, some Contentstack integrations used limit=0 as shorthand for returning every matching record. Contentstack says that behaviour could create timeouts on large stacks. The platform now treats zero, empty and non-numeric values as invalid for an unlimited fetch and applies the endpoint's default page size.
The response may still be structurally valid. That means a health check that asks only whether the API returned 200 can pass while the business receives incomplete content.
| Caller | What partial data can look like | Business impact |
|---|---|---|
| Website or static build | Only the first group of pages, products or locations is generated | Missing URLs, stale navigation or incomplete campaigns |
| Search indexing | The job replaces a complete index with its first page | Valid content disappears from onsite search |
| Migration or export | The script reports success with fewer records than the source | Incomplete cutover, archive or compliance evidence |
| Reporting and dashboards | Totals fall without a corresponding API error | Incorrect operational or marketing decisions |
| Integration feeds | CRM, PIM, DAM or personalisation receives a truncated set | Broken customer journeys and inconsistent channels |
The practical control is to treat record completeness as part of correctness. Status code, schema and latency matter, but the processed total must also match the expected result set.
Move from one unlimited request to verified batches
Find every caller that may rely on limit=0
Start with deployed behaviour, not a search of the main website repository alone. The parameter may be assembled in configuration, a shared SDK wrapper, a low-code workflow or a former agency's integration.
- Search code and configuration. Look for
limit=0, empty limit variables, generic query builders and wrappers that translate a value such asallinto zero. - Inventory scheduled jobs. Include exports, imports, search indexing, sitemap generation, cache warming, reporting, content mirroring and backup processes.
- Inspect external consumers. Ask CRM, DAM, PIM, ecommerce, personalisation, translation and analytics owners whether they call CDA or CMA directly.
- Capture endpoint context. Record the API, resource, environment, locale, branch, filters, sort order, SDK version, credentials, owner and expected record volume.
- Check historical runs. A sudden drop to a round number near 100 is a useful signal, but absence of that pattern is not proof that every caller is safe.
Also check empty or non-numeric limit values. A configuration screen, environment variable or URL builder can produce those variants even when the source code contains no literal zero.
Use a complete pagination loop
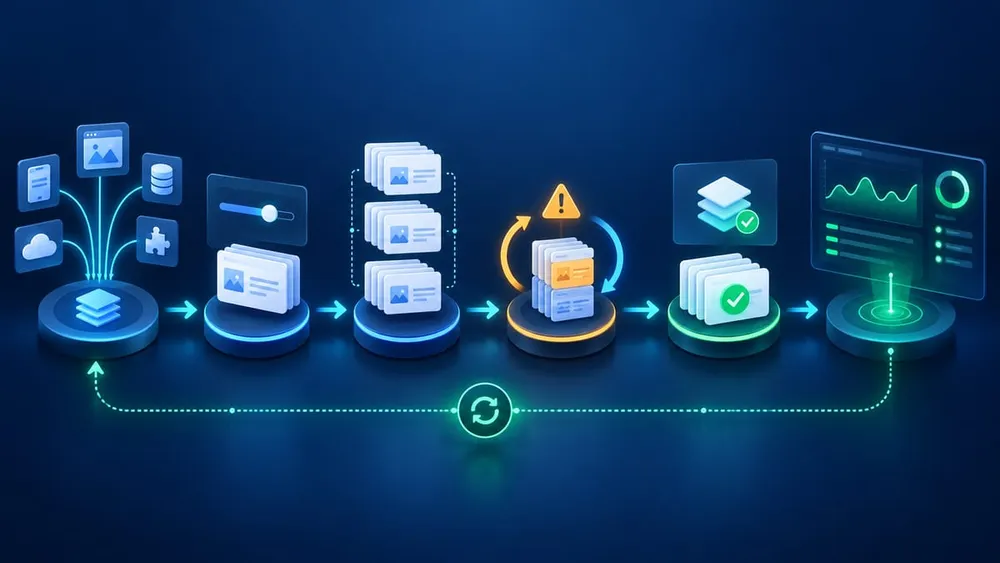
Contentstack recommends a positive limit, advancing with skip, and using include_count=true to retrieve the total where the endpoint supports it. The exact page size and response shape are endpoint- and SDK-specific, so confirm them against the reference for the caller you are changing.
A robust implementation follows this sequence:
- Request the first page with an explicit positive page size and a stable filter and sort order.
- Capture the returned total when available and add the page's records to the result set.
- Advance
skipby the number of records actually returned, not merely by a hoped-for page size. - Continue until the processed count reaches the returned total or a documented short final page proves completion.
- Deduplicate by stable identifiers and report a mismatch if the unique processed total differs from the expected total.
pageSize = endpointSafePositiveLimit
skip = 0
expected = unknown

repeat:
  page = fetch(limit=pageSize, skip=skip, include_count=(skip == 0))
  if expected is unknown and page.count exists: expected = page.count
  processIdempotently(page.items)
  skip = skip + page.items.length
until (expected is known and skip >= expected) or page.items.length < pageSize

assert uniqueProcessed == expected when expected is known
Do not copy one maximum across every API. Contentstack's JavaScript Delivery SDK currently documents 100 items by default and a maximum of 250 for multiple-entry queries, while individual CMA resources can define their own limits and count behaviour.
Make the loop safe when content changes mid-run
Offset pagination is simple, but a changing dataset can move records between pages. If entries are added, removed or reordered while a long job is running, the integration can duplicate or skip items unless the design accounts for change.
- Use a stable ordering. Choose a documented deterministic order with a unique tie-breaker where the API permits it.
- Process idempotently. Upsert by Contentstack UID and relevant locale or branch rather than assuming every page is new.
- Store progress carefully. Record the filter, environment, page position, last successful identifiers and run ID so a retry does not blindly restart destructive work.
- Reconcile at the end. Compare unique processed identifiers and totals with the source, then flag additions or deletions that occurred during the run.
- Separate retries from pagination. Retry only the failed request with bounded backoff; do not advance the cursor or offset until that page is accepted.
For a delivery mirror or offline store that needs an initial dataset followed by changes, evaluate Contentstack's Sync API. It uses a pagination_token when a sync result exceeds 100 records and produces a sync_token for later delta updates. That can be a better fit than repeatedly walking the entire content set, but it has different semantics and should be adopted deliberately.
Test above the default page size
A test stack with 12 entries cannot expose a first-page truncation bug. Build test data or use an approved representative environment that crosses the relevant endpoint's default and chosen page size.
| Scenario | What to verify | Evidence to keep |
|---|---|---|
| Exactly one page | No unnecessary extra processing and correct total | Request count and unique record count |
| One page plus one record | The second page is fetched | Processed identifiers across both pages |
| Several full pages | Termination does not rely only on a short page | Returned total and final reconciliation |
| Zero matches | The job completes cleanly without looping | Zero expected and zero processed |
| Duplicate or changing records | Idempotency and reconciliation detect movement | Unique IDs, warnings and final status |
| HTTP 429 or transient 5xx | The same page is retried with bounded backoff | Retry log without skipped offsets |
| Restart after interruption | Resume or replay does not duplicate side effects | Run checkpoint and destination totals |
| Legacy parameter variants | Zero, empty and non-numeric values are removed or rejected by your code | Automated regression assertions |
Run the end-to-end customer or operational journey as well. A function can return every record while a downstream indexer, CSV writer or database batch silently drops later pages.
A four-step plan for Australian teams
Prioritise visibility, then change and verify the integrations with the highest business impact.
1. Inventory
Name every CDA and CMA caller, owner, endpoint, dataset and downstream business process.
2. Measure
Compare historical, expected and current record totals; rank callers by impact and likelihood.
3. Remediate
Add explicit positive limits, complete pagination, idempotency, retry controls and reconciliation.
4. Release
Run production-shaped tests, deploy gradually, verify totals and retain rollback or replay evidence.
Monitor completeness, rate limits and downstream outcomes
Pagination adds requests, so monitoring should cover both completeness and API pressure. Contentstack currently documents a default Content Management API limit of 10 read requests per second per organisation and HTTP 429 when the allowance is exceeded; plan-specific limits can differ.
Track at least:
- expected, returned and unique processed records for each run;
- page count, page size and duration by endpoint and environment;
- zero-result runs and suspicious round-number totals;
- HTTP 429 and transient server failures, retry count and retry exhaustion;
- duplicate identifiers, reconciliation differences and restart events;
- downstream index, export, build or database totals;
- the release version and owning team for every caller.
Make a count mismatch a failed run, not an informational log. For destructive syncs, avoid replacing or deleting destination records until the source walk has completed and reconciled. A truncated source response should not be allowed to erase valid downstream data.
Questions to ask your developer or support partner
- Which websites, builds, exports, indexes and integrations call Contentstack CDA or CMA?
- Do any callers send
limit=0, an empty limit or a non-numeric value? - What are the documented default and maximum page sizes for each endpoint and SDK?
- Does every job verify the expected total against unique records processed?
- How does the loop behave if content changes during a long run?
- Can a failed page retry without skipping data or duplicating side effects?
- Have we tested with more records than the default page size?
- Would the Sync API better fit any persistent content mirror?
- Who receives an alert when source and destination totals differ?
A credible answer includes a caller inventory, endpoint-specific pagination rules, automated tests, reconciliation evidence and named ownership. A successful HTTP response is not enough.
Sources checked
- Contentstack changelog: Changes to the limit Query Parameter in CDA and CMA Requests
- Contentstack Content Delivery API reference
- Contentstack CDA query-parameter reference
- Contentstack JavaScript Delivery SDK reference
- Contentstack Sync API documentation
- Contentstack Content Management API reference
- Contentstack CMA job-status pagination reference